AI tools for audiovisual production
It is now clear to everyone, and we at EuraCreative have been convinced of this for some time: artificial intelligence is bound to have an impact on the professions, processes, training and day-to-day lives of students, entrepreneurs and staff within our ecosystem.
- Written by Louise Blas

A look back at the first IApéro at La Plaine Images, a monthly event designed by and for professionals in the cultural and creative industries.
For this inaugural event, we were joined by Julien Frisch, a former incubatee, AI consultant and one of BPI France’s lead advisors for the AI Booster France 2030 programme, and Rémi Auguste, who holds a PhD in computer science and is the founder of Weaverize, a company based at La Plaine Images for the past seven years.
Generative artificial intelligence offers growing opportunities for cost reduction in the retail sector, a major consumer of commercial visuals.
Historically, retail companies had to organise photo shoots, which involved transporting thousands of products to venues specially hired for the occasion, setting up the scenes, managing the lighting, taking the photographs, and carrying out post-production work… With AI, Rémi Auguste gives us a detailed overview of the tools he uses to overhaul the workflow for this large-scale production:
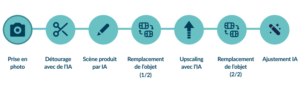
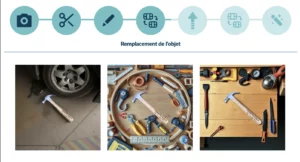
In summary, products are now photographed in a traditional studio and virtually integrated into different settings using AI solutions. But which tools are best for each stage? A brief overview is in order, with a focus on open-source software:
AI-powered background removal
This can be done almost instantly using free online services (a simple search for “remove background”), but certain tools meet the expected professional standards, such as removebg.
Segment Anything Model (SAM), a new AI model developed by Meta’s R&D team, enables any object to be cut out from any image with a single click, thanks to semantic discrimination. On the open-source software front, Yolo is a good alternative.
AI-generated images
To create visuals that incorporate the photographed product, use Stable Diffusion or Flux. Commercial alternatives include Midjourney, Dall-E and Stable Diffusion WebUI Forge. In reality, each tool has its own specific features in terms of control and output rendering: Flux is a top choice if you want to fine-tune the specific details you require in your generation.
These tools also handle image upscaling (by adding pixels), which is essential for a professional-looking result or for certain applications, such as print.
Videos featuring AI
There are many solutions available, but here is a tried-and-tested selection:
How to use LoRA
To complement this initial set of tools, Rémi Auguste takes a moment to discuss a way of taking generative models a step further: LoRA.
LoRA stands for Low-Rank Adaptation and is a method for creating lightweight sub-models that can be layered onto existing AI models, such as Stable Diffusion. What’s the benefit? Instead of training a complete model—with all the data processing requirements that entails—LoRAs allow you to add new styles as an overlay, using just 10 to 20 MB of additional parameters. Training can be carried out using as few as 10 images, giving you control over a small collection of objects.
This approach to fine-tuning is particularly useful for those seeking a specific, recognisable style (think of the Lego-style rendering, for example!), with libraries such as Hugging Face (among others) offering a selection of pre-trained LoRAs.
Generative AI for sound processing
In the field of speech synthesis, progress has been exponential in recent years: for a long time, tools used a concatenative approach, meaning that phonemes were strung together by mapping syllables to sounds, which was effective but sounded very unnatural. Now, generative AI enables much higher-quality output. ElevenLabs is one of the market’s leading tools and includes a host of features to bring your projects to life.
Converting text to speech using AI
ElevenLabs enables you to process a text stream to produce high-quality audio, a process known as text-to-speech.
The tool offers a wide range of voice-related features, including the ability to train the system on your own voice (through a process known as cloning) to ensure the output sounds as natural as possible. It therefore enables you to manage:
- ‘traditional’ speech synthesis, with the option to translate directly into another language
- voice-overs and dubbing
- the rapid creation of audiobooks
Cloning a voice takes between 1½ and 2 hours, as the model needs to be trained to recognise the voice by providing a set of audio samples. After that, it couldn’t be simpler: the tool generates the desired output in a matter of seconds.
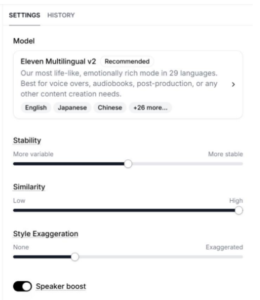
An example of a possible configuration on Eleven Labs
Lip-syncing with AI
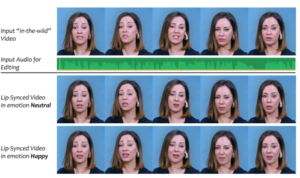
VideoReTalking is an open-source model that allows you to edit the faces in a video so that the lips move in sync with new audio.
Video image animation using AI
Several open-source tools speed up part of the animation process:
- AniPortrait allows you to animate the lines in a static image using audio or video
- Efficient-Live-Portrait allows you to animate the lines of an image by cloning the lines from a video
- LivePortrait specialises in animating paintings:
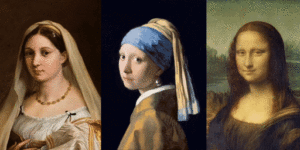
As you’ll have realised, there is a wealth of tools available, and it’s important to choose the right ones depending on your needs: this is one of the aims of the IApéros Plaine Images events, but not the only one!
At our upcoming events, we’ll be focusing specifically on a particular use case, a challenge, a best-practice example or a tool demonstration… so that this monthly event becomes a powerful catalyst for change for audiovisual professionals!